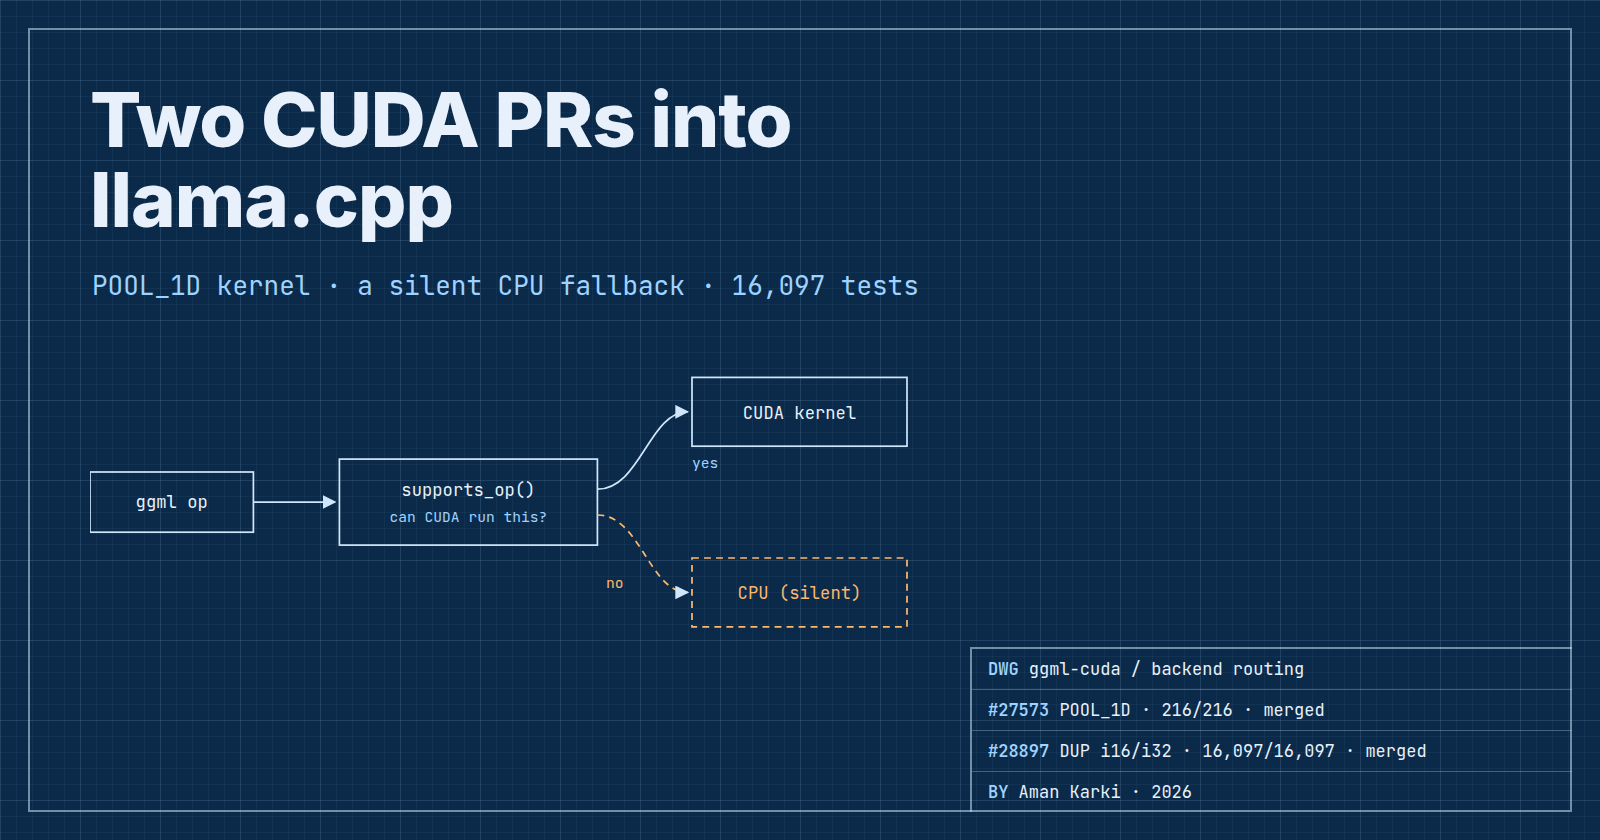
Two CUDA PRs into llama.cpp, and what they taught me about a 100K-star codebaseA 95-line pooling kernel, a 9-line fix for a silent CPU fallback, and how ggml decides where your ops runSep 27, 2026·11 min read·4