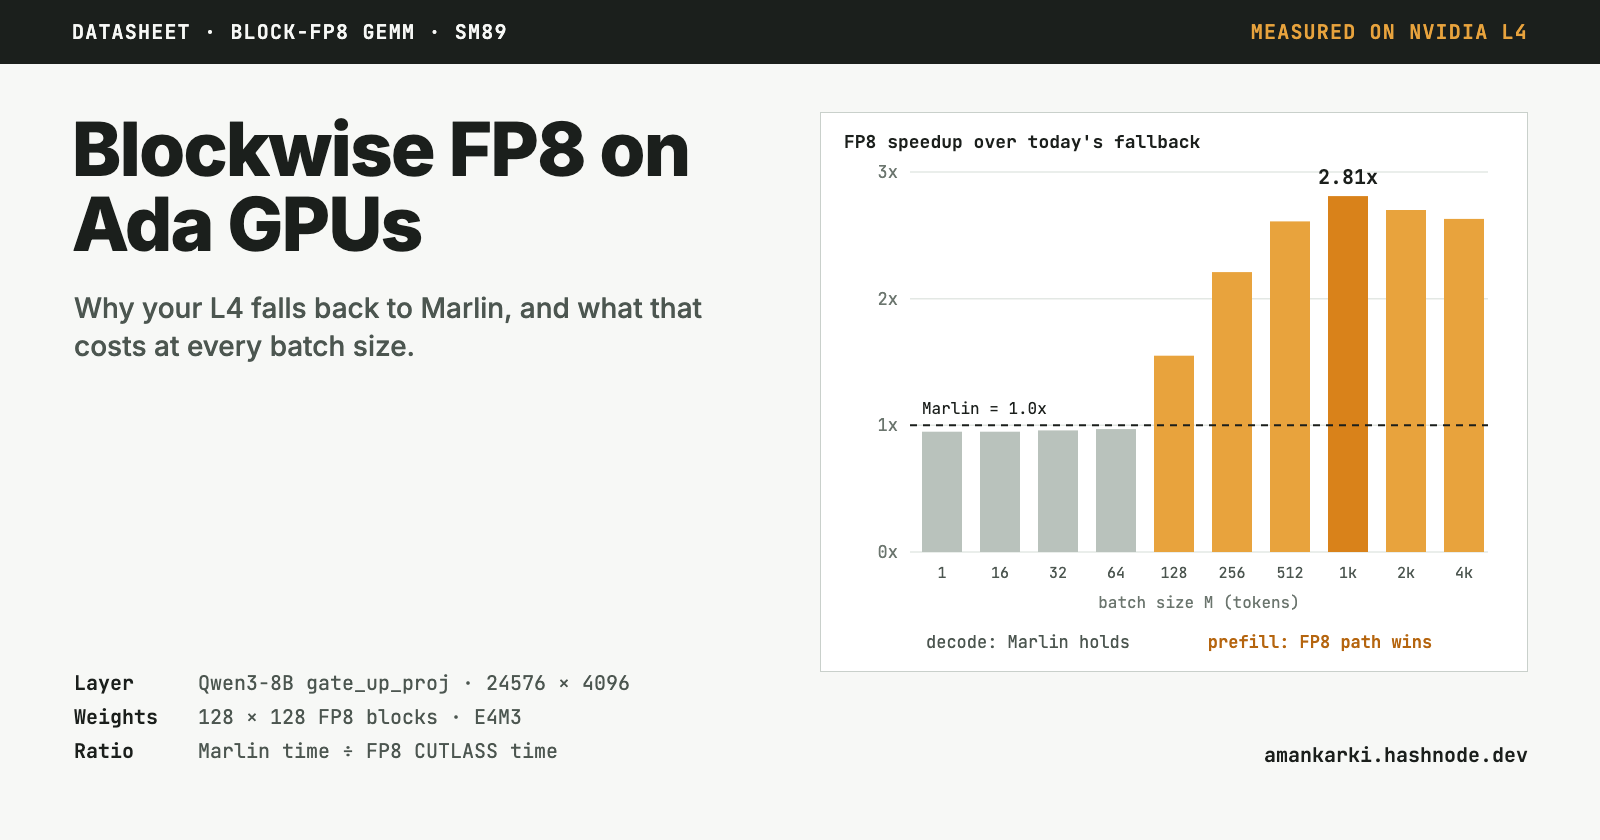
Blockwise FP8 on Ada GPUs, part 2: my kernel was correct and 4x too slow
How I found register spills in the main loop, fixed them, and got a 1.42x end-to-end speedup on an L4
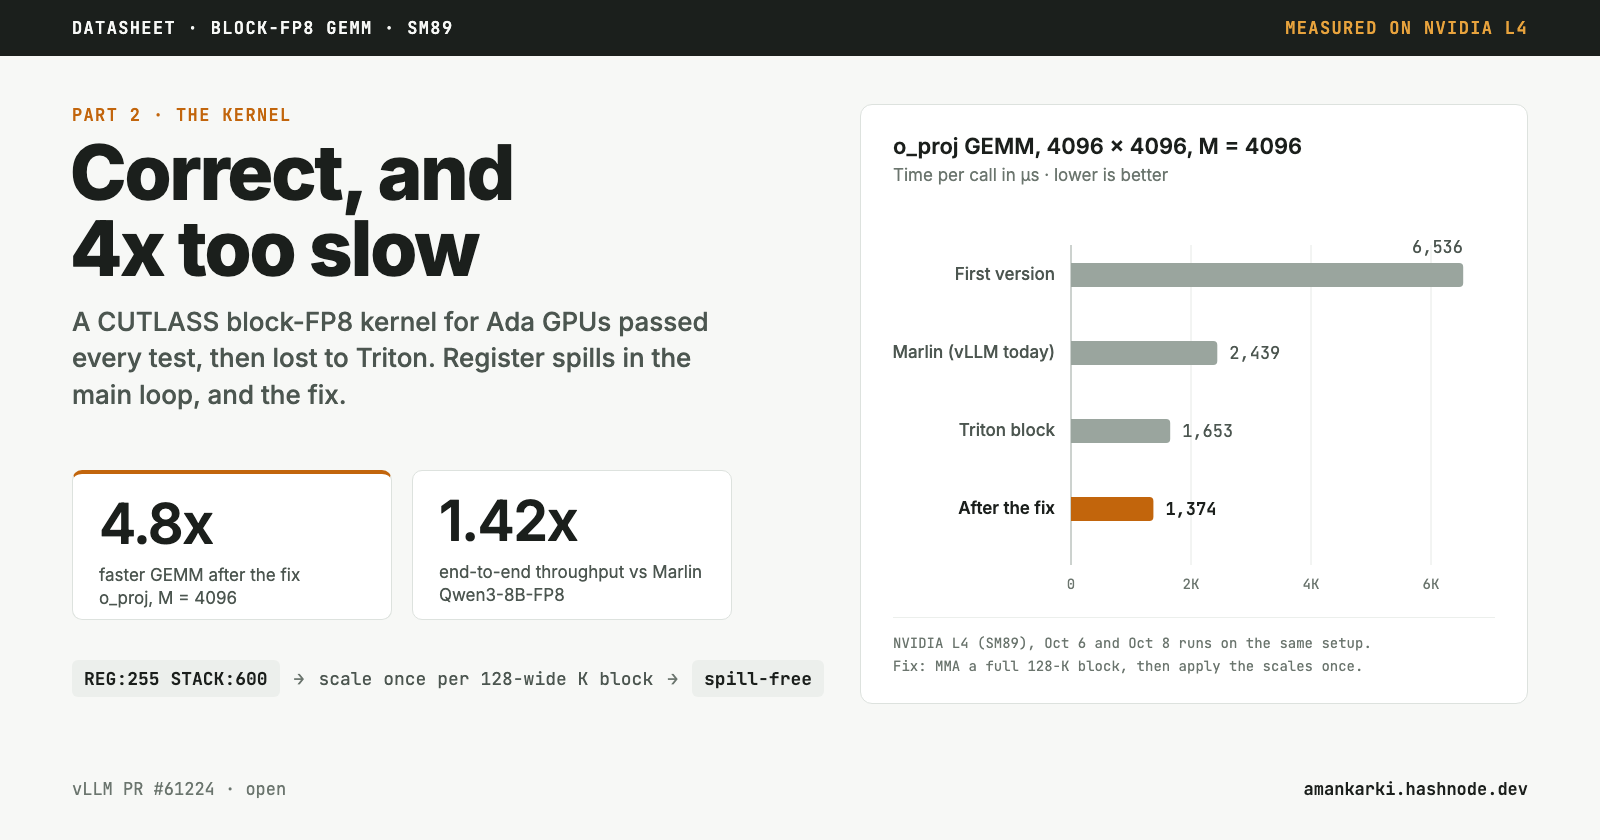
How I found register spills in the main loop, fixed them, and got a 1.42x end-to-end speedup on an L4
What 128×128 block scaling is, why it needs its own kernel, and what the missing kernel costs on a real L4